Your AI. On your phone. Offline.
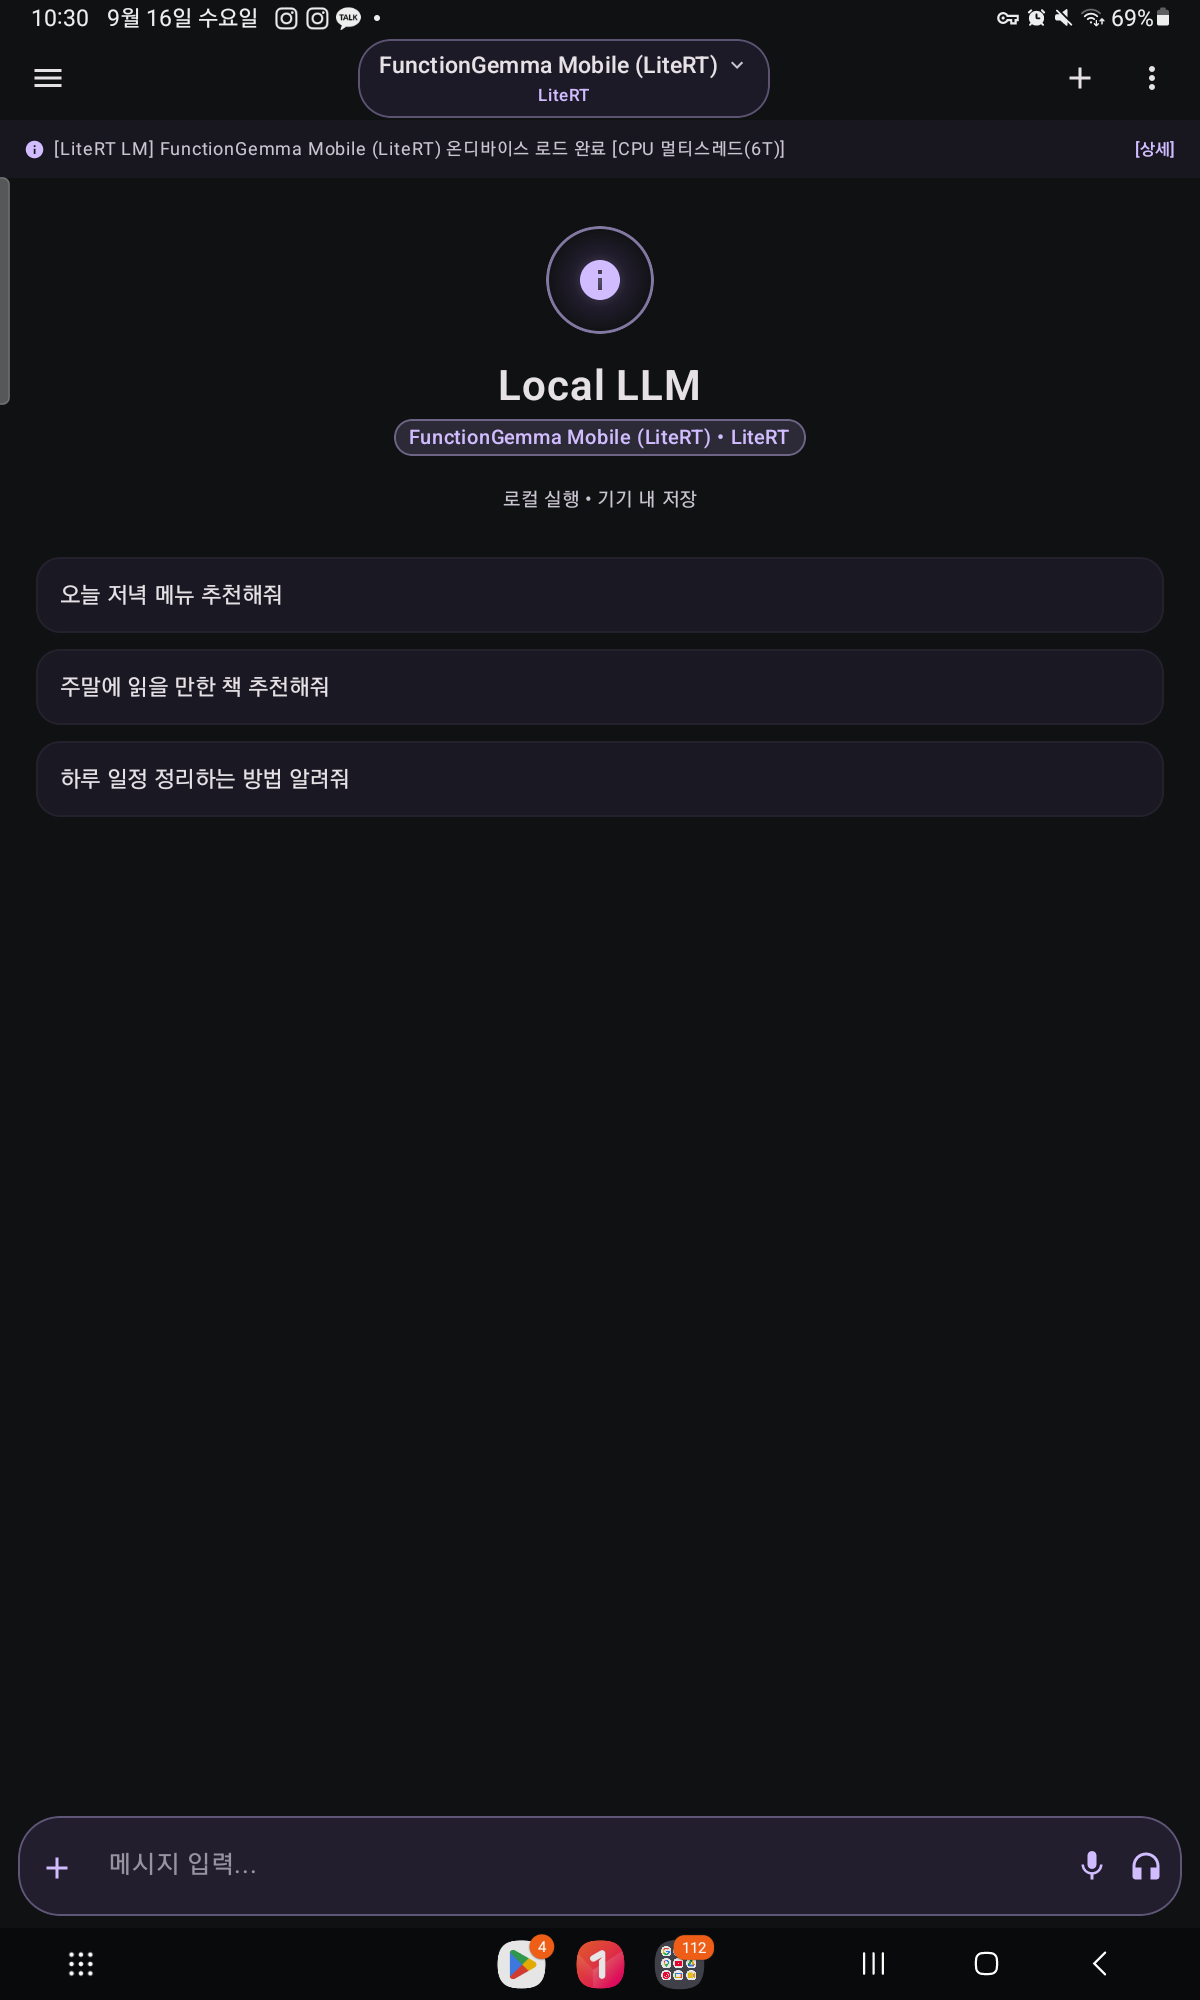
A privacy-first, fully offline on-device LLM chat and server for Android. Run state-of-the-art models directly on your CPU, GPU and NPU - no cloud, no API keys, no telemetry. Custom glass UI, instant English/Korean switching, tool use via a native MCP client, and an experimental first-party MoE engine built in the open.
Why it's different
Most "local LLM" apps give you one engine. Local LLM Android runs two, behind one interface.
llama.cpp runtime
- Any GGUF model from Hugging Face (Q4_K_M, Q8_0...)
- Qwen, Llama 3, DeepSeek-R1 and more
- CPU multi-threading + GPU layer offload
- Reasoning (think tags) and multimodal support
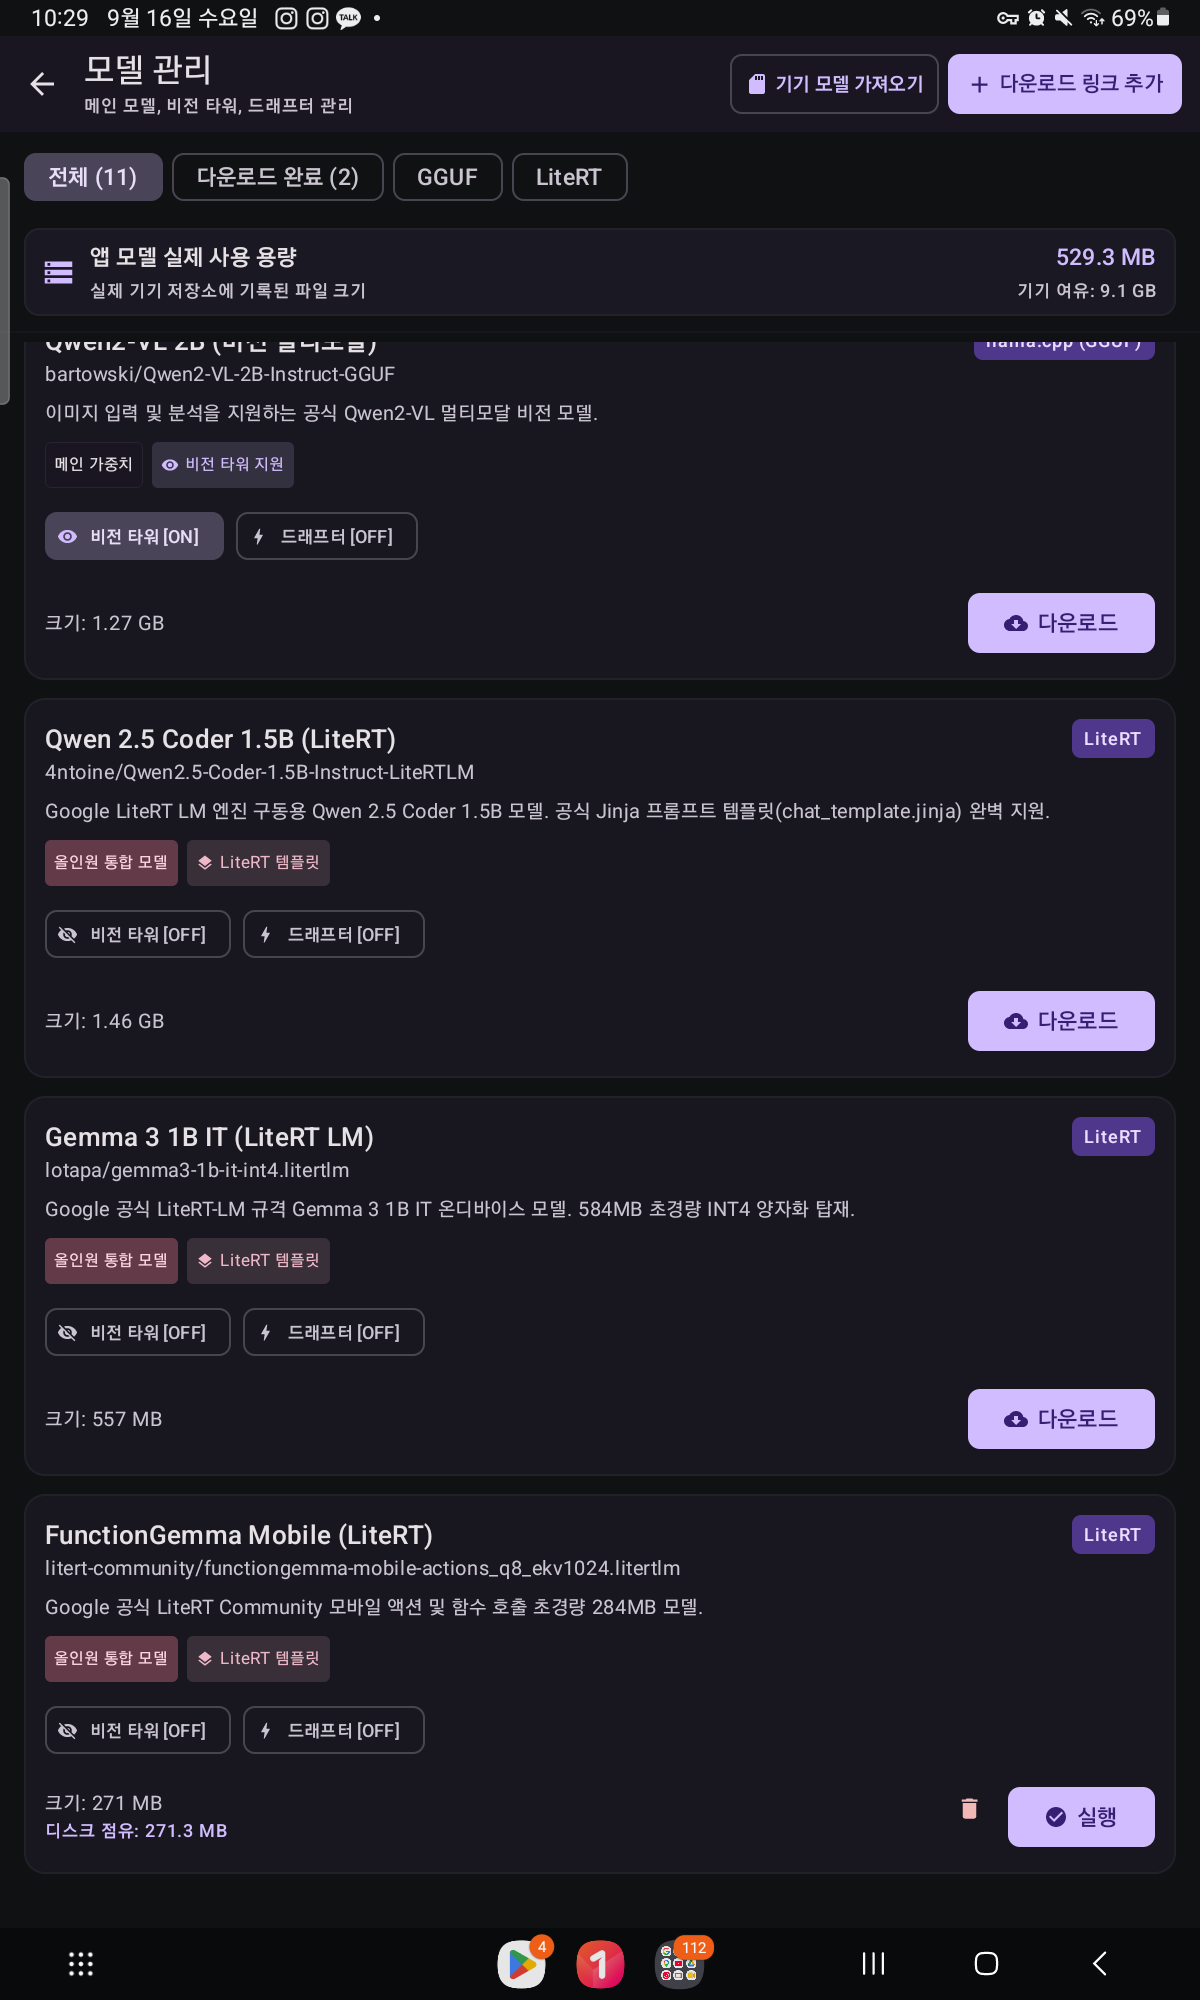
Google LiteRT-LM runtime
- Native NPU / GPU acceleration (OpenCL, Vulkan)
- Gemma 2 / 3 and mobile-optimized binaries
- Low power draw, tuned for Snapdragon / Tensor / MediaTek
- Real benchmark metrics from the native core
Hardware-backed encryption
Chats are AES-256-GCM encrypted with non-exportable keys generated in the Android Keystore (hardware backing is device-dependent and read back via KeyInfo). No silent fallbacks.
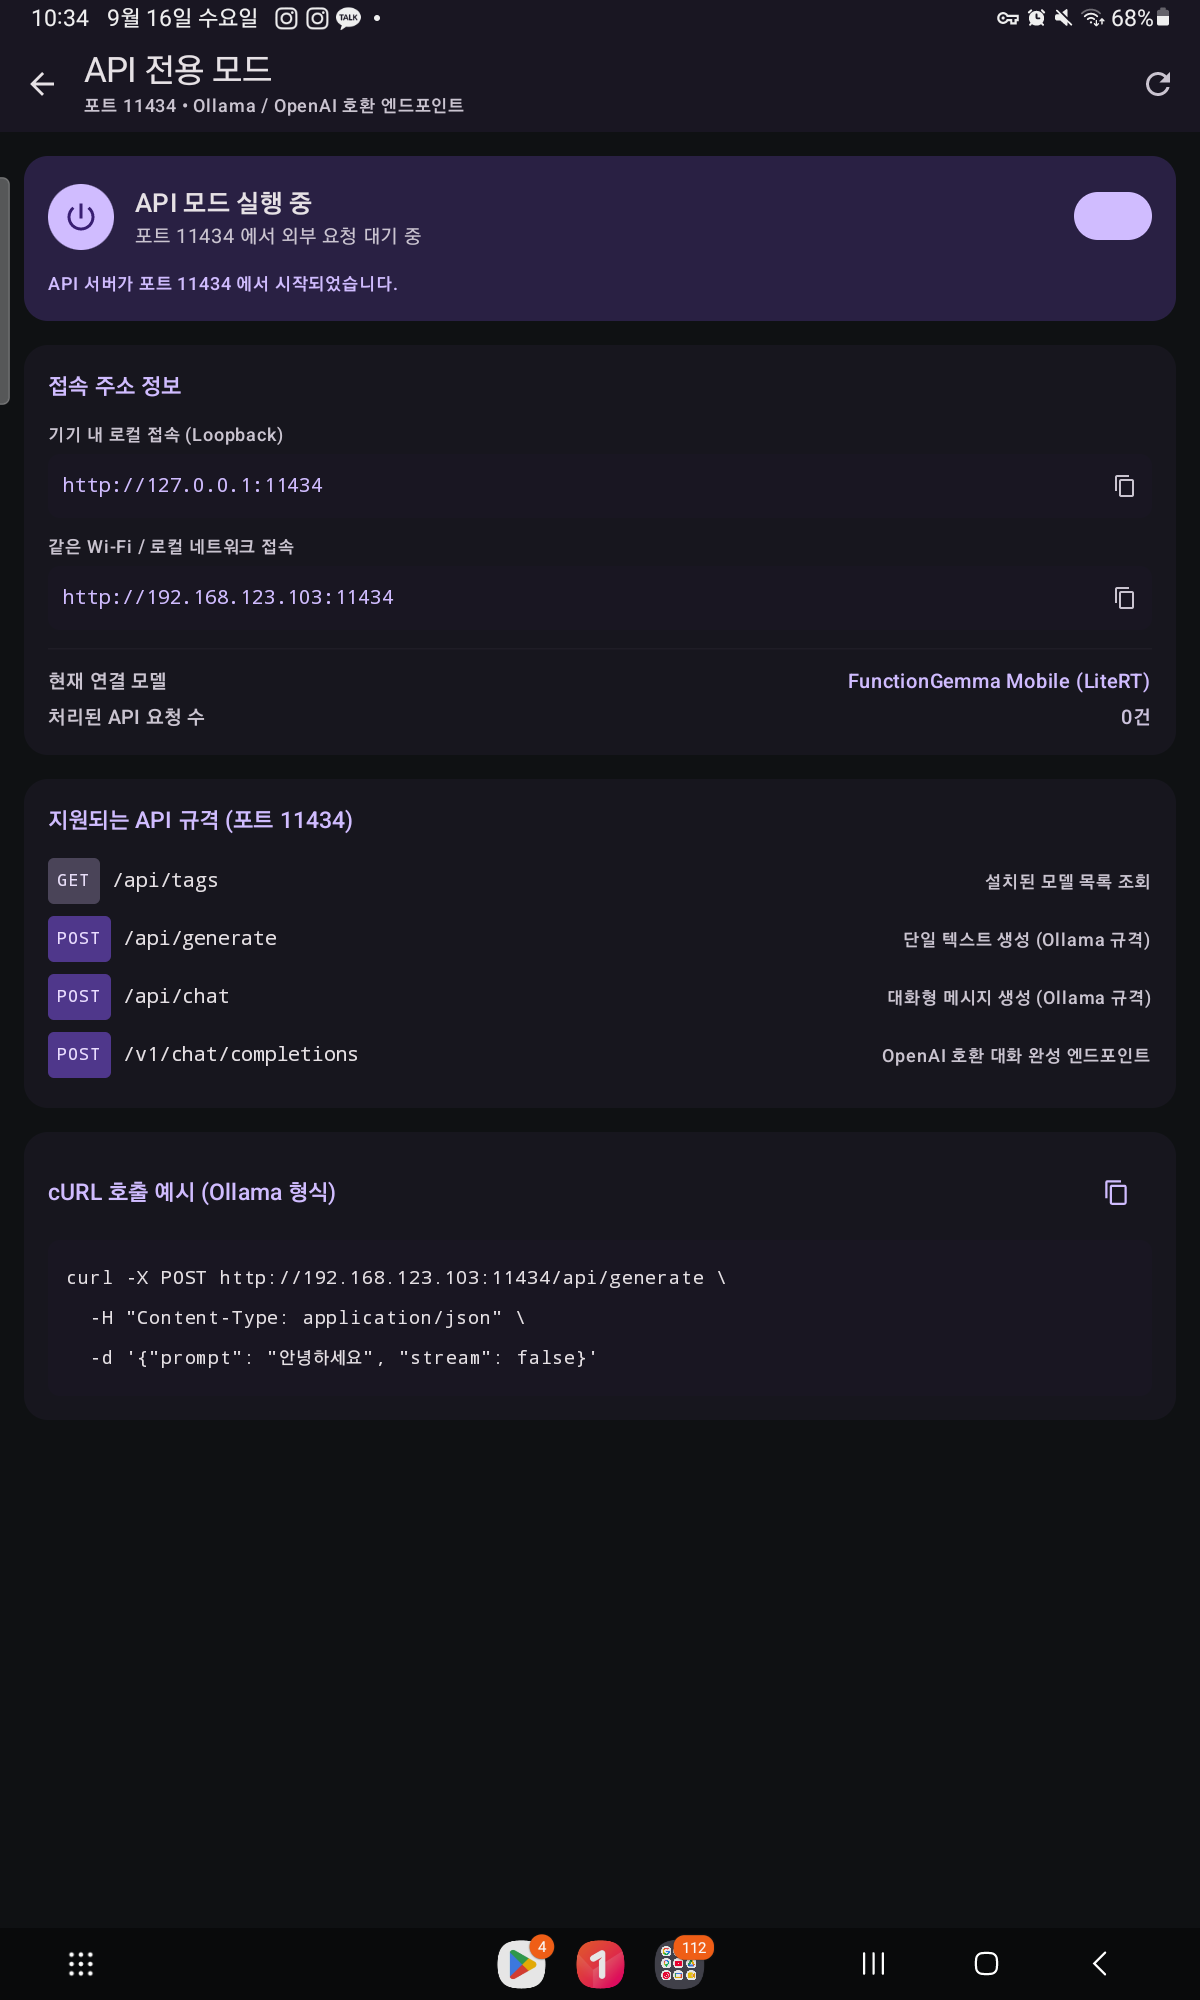
Ollama / OpenAI-compatible server
Port 11434 server on-device. Loopback-only by default, optional LAN binding with bearer-token auth. Drop-in for your existing tools.
Real-time benchmarking
Token-level prompt speed and generation speed (tokens/s) measured via native tokenizers, shown on every message.
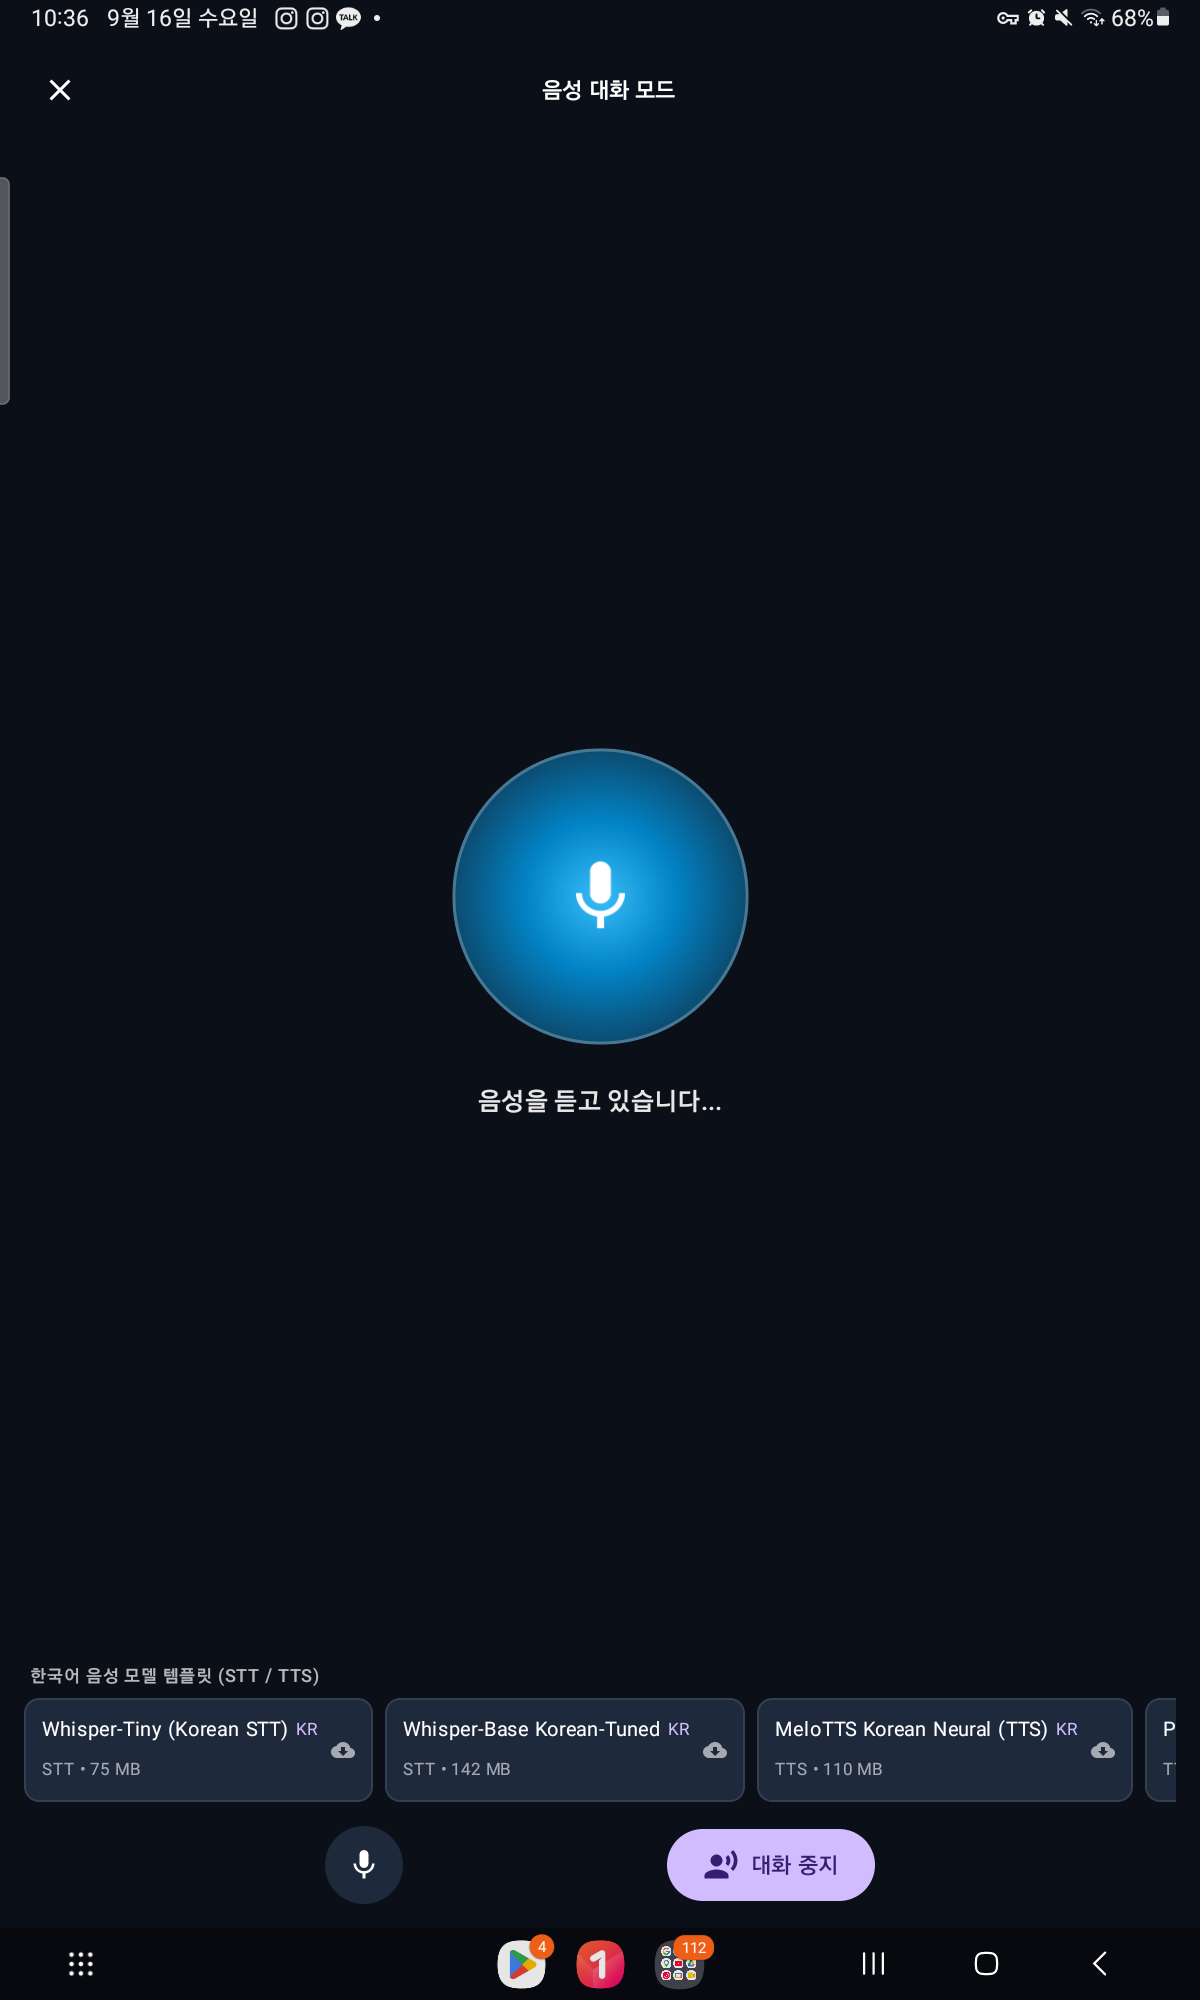
Voice mode with local Whisper STT
Hands-free loop: on-device Whisper speech-to-text, LLM generation, text-to-speech. Animated voice orb, zero cloud round-trips.
Reasoning-aware streaming
DeepSeek-R1 style think tags are parsed reliably even when split across streaming chunks.
MCP client
Native Model Context Protocol client with per-session isolation guards, bringing tool use into on-device chats.
First-party glass UI
Material3 stripped out. A custom glass design system covers every screen, with instant English/Korean switching built in.
OOM protection
Footprint estimate (weights + KV cache) before load, an in-flight marker so a kill mid-inference is detected on the next start, automatic setting reduction after an abnormal exit, and a live memory watchdog that stops generation before Android kills the app.
In the lab: SDengine
A first-party MoE-only inference core, built in the open as the :engine module. GGUF reader, BPE tokenizer, paged expert streaming, portable C++ JNI reference (real math is JVM scalar kernels; NEON pending). Numerical validation against real MoE weights runs manually/nightly via range streaming, plus end-to-end generation over gated-expert GGUFs. Imported models default to llama.cpp; SDengine is strictly opt-in per model, advisories stay visible, and a failed load falls back to llama.cpp. Experimental - runs, but not for production yet. Dense engines (llama.cpp / LiteRT-LM) remain the production path.
Build from source
Apache-2.0 licensed. Clone, build, ship.
git clone https://github.com/zmxnpquryet-gif/Localllmandroid.git
./gradlew assembleDebug      # build
./gradlew testDebugUnitTest  # test